Website concept · October 2026Private mock-up for review

Evidence communication

Will your health content be understood and used?

Medical, legal and regulatory review checks accuracy and compliance. An early diagnosis also asks what evidence shows that the intended reader will trust, understand and act on the content.

Bring patient or clinician materials, trial content, or a workflow that produces them—with or without AI assistance. People’s Evidence Lab was founded by Steve Watt.

Anonymized case · Communication study design

Measuring understanding alongside preference

A healthcare communication team was planning a study of patient-facing infographics. The planned comparison asked which materials patients preferred. Their intended use raised another question: did patients correctly understand the messages?

PEL reviewed the study in relation to the people who would use the materials and recommended measuring comprehension accuracy alongside preference, including a secondary-endpoint option. This meant testing whether readers could identify the intended messages, rather than relying on preference or self-rated clarity.

The contribution was a specific recommendation to broaden what the study would measure. This case illustrates study-design advice; it does not establish improved patient understanding or health outcomes.
An early diagnosis

Look beyond the final review.

You receive a short written diagnosis of the barriers your team can act on, and the questions that need testing with intended readers. The questions below come from EvLander™, PEL’s approach to assessing how content is received by the people it is for.

The diagnosis does not promise behavior change or better health outcomes. It is not compliance or safety validation of an AI system.

Will the content clear its review?

Does the draft support the accuracy and compliance checks your medical, legal and regulatory reviewers need to make?

Will the intended reader trust and understand it?

Are the language, explanation and source information usable by the people the content is for? What evidence supports that judgment?

Can it be delivered and acted on where it is used?

Who hands it over, when and with how much time? What must the reader do next, and how will anyone know whether they can?

What happens next

Diagnosis first. Then the work it identifies.

Diagnosis

Review the draft, the people it is for and the setting where they will use it. Identify what can be changed before final review.

Co-creation

Where needed, agree a process in which patients contribute to design decisions, rather than only react to finished content.

Testing

Where needed, measure whether intended readers trust, understand and can act on the content. Agree measures before testing.

Patient work is scoped case by case. Recruitment, fieldwork, consent, privacy, payment and any required ethics review are agreed before work begins.

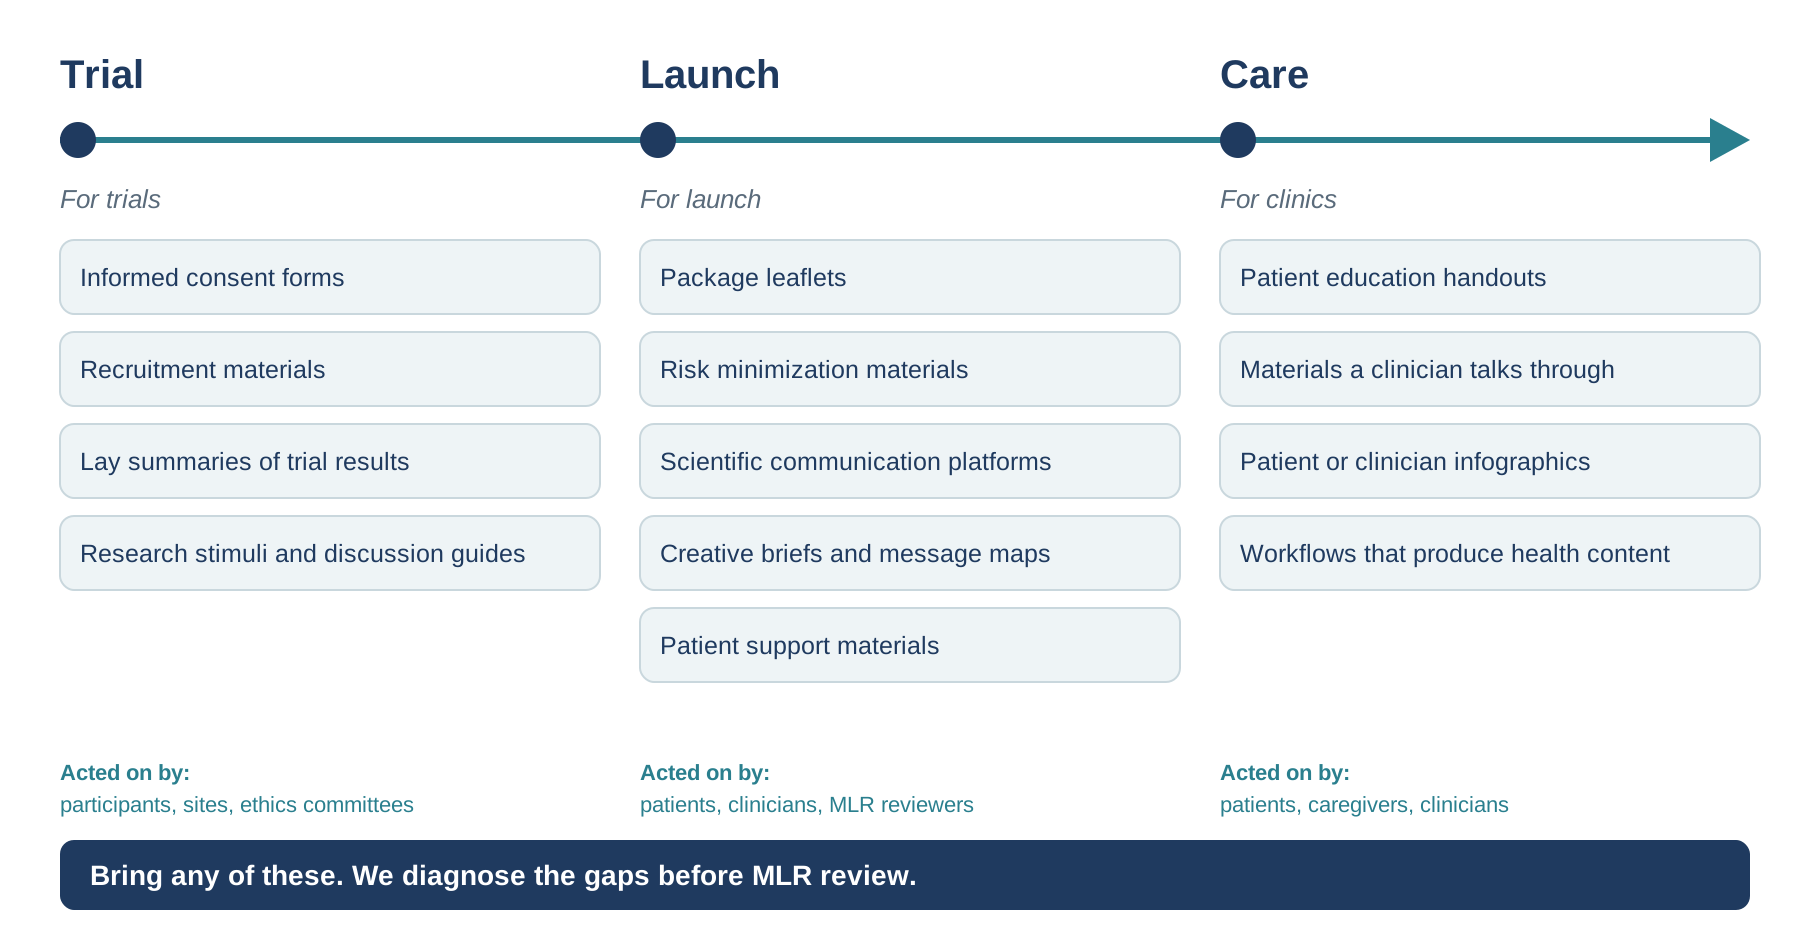
What you can send

Content across trials, launch and care.

Trial

For trials

  • Informed consent forms
  • Recruitment materials
  • Lay summaries of trial results
  • Research stimuli and discussion guides

Acted on by: participants, sites, ethics committees.

Launch

For launch

  • Package leaflets
  • Risk minimization materials
  • Scientific communication platforms
  • Creative briefs and message maps
  • Patient support materials

Acted on by: patients, clinicians, MLR reviewers.

Care

For clinics

  • Patient education handouts
  • Materials a clinician talks through
  • Patient or clinician infographics
  • Workflows that produce health content

Acted on by: patients, caregivers, clinicians.

Bring any of these. We diagnose the gaps before MLR review.

Start before final review, before launch or before sites are activated. PEL does not produce content at volume.

Published communication methods

Understanding and action are separate questions.

The Patient Education Materials Assessment Tool provides a reference for examining the understandability and actionability of patient materials.

PEMAT does not assess factual accuracy or completeness. Its scores also do not establish what your intended readers understood; AHRQ recommends testing materials with patients.

An inspectable question · Coauthored essay

When AI empathy varies: a question worth asking

Steve Watt and Maya Watt · 3 February 2026

The essay asks what an average empathy score can hide about variation across responses. For teams reviewing AI-assisted content, it offers a question to examine about consistency. It is a research argument, not evidence that a particular workflow is safe.

Related research

Consistency matters when AI helps produce content.

PEL’s registered language model studies examine variation in expressed empathy across responses. Steve Watt is also a co-author of an ISPOR-listed study comparing healthcare practitioners’ preferences for infographics made with and without generative AI assistance. That study concerns the materials examined; it does not validate PEL’s diagnostic service.

Review the draft while it can still change.

Bring the content, its intended readers and the point at which it becomes costly to revise. A 30-minute call establishes whether a diagnosis would help.

Request a call